
PostegreSQL 17 is a signal to both engineering leaders and business stakeholders that open-source infrastructure has closed most of the remaining gaps with proprietary databases with faster recovery, smaller backups, and zero-downtime replication upgrades translate directly into fewer outage hours, lower storage spend and reduced operational risk. At the same time, a maturing extension ecosystem spanning vector search, geospatial analytics, time-series workloads, and distributed scale signify that organizations can consolidate what used to require three or four specialized (and separately licensed) systems into a single, well-understood platform.
At leadership scale, PostgreSQL 17 is a lower-risk foundation for AI, analytics, and multi-region applications. It is a lever for reducing licensing spend, shrinking maintenance windows, and avoiding the vendor lock-in that has historically constrained negotiating power with legacy database vendors. This article expands the technical architecture of PostgreSQL 17 with the business context leadership teams need to build a sound investment case.
PostgreSQL 17 introduces several enhancements that improve backup efficiency, SQL/JSON processing, logical replication, and database maintenance. Combined with its rich extension ecosystem, PostgreSQL continues to be one of the most powerful open-source relational databases for enterprise workloads.
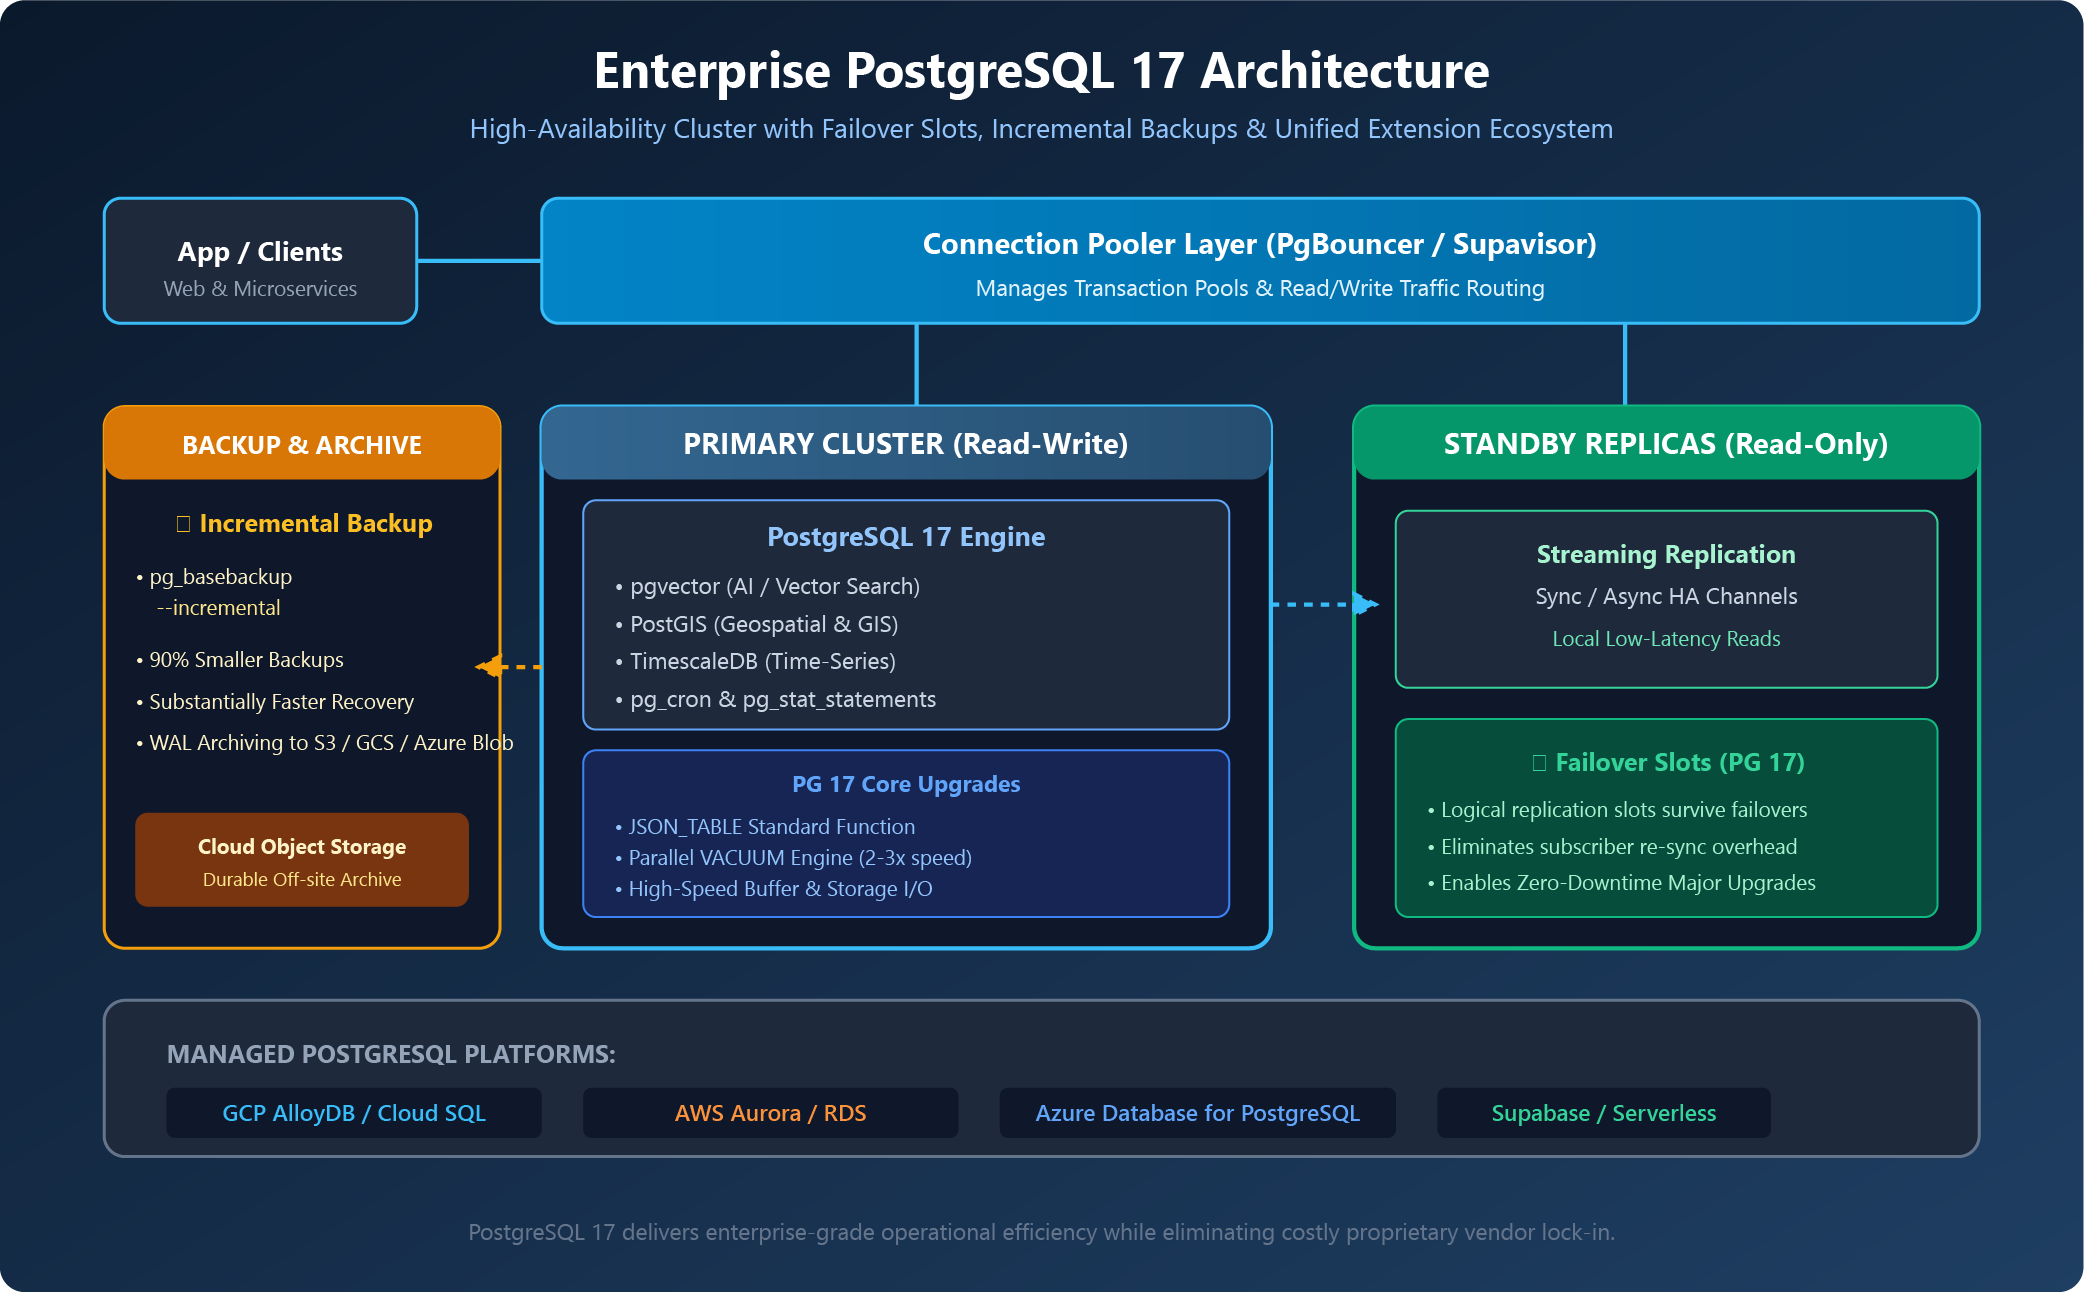
Reference Architecture: Enterprise PostgreSQL Deployment
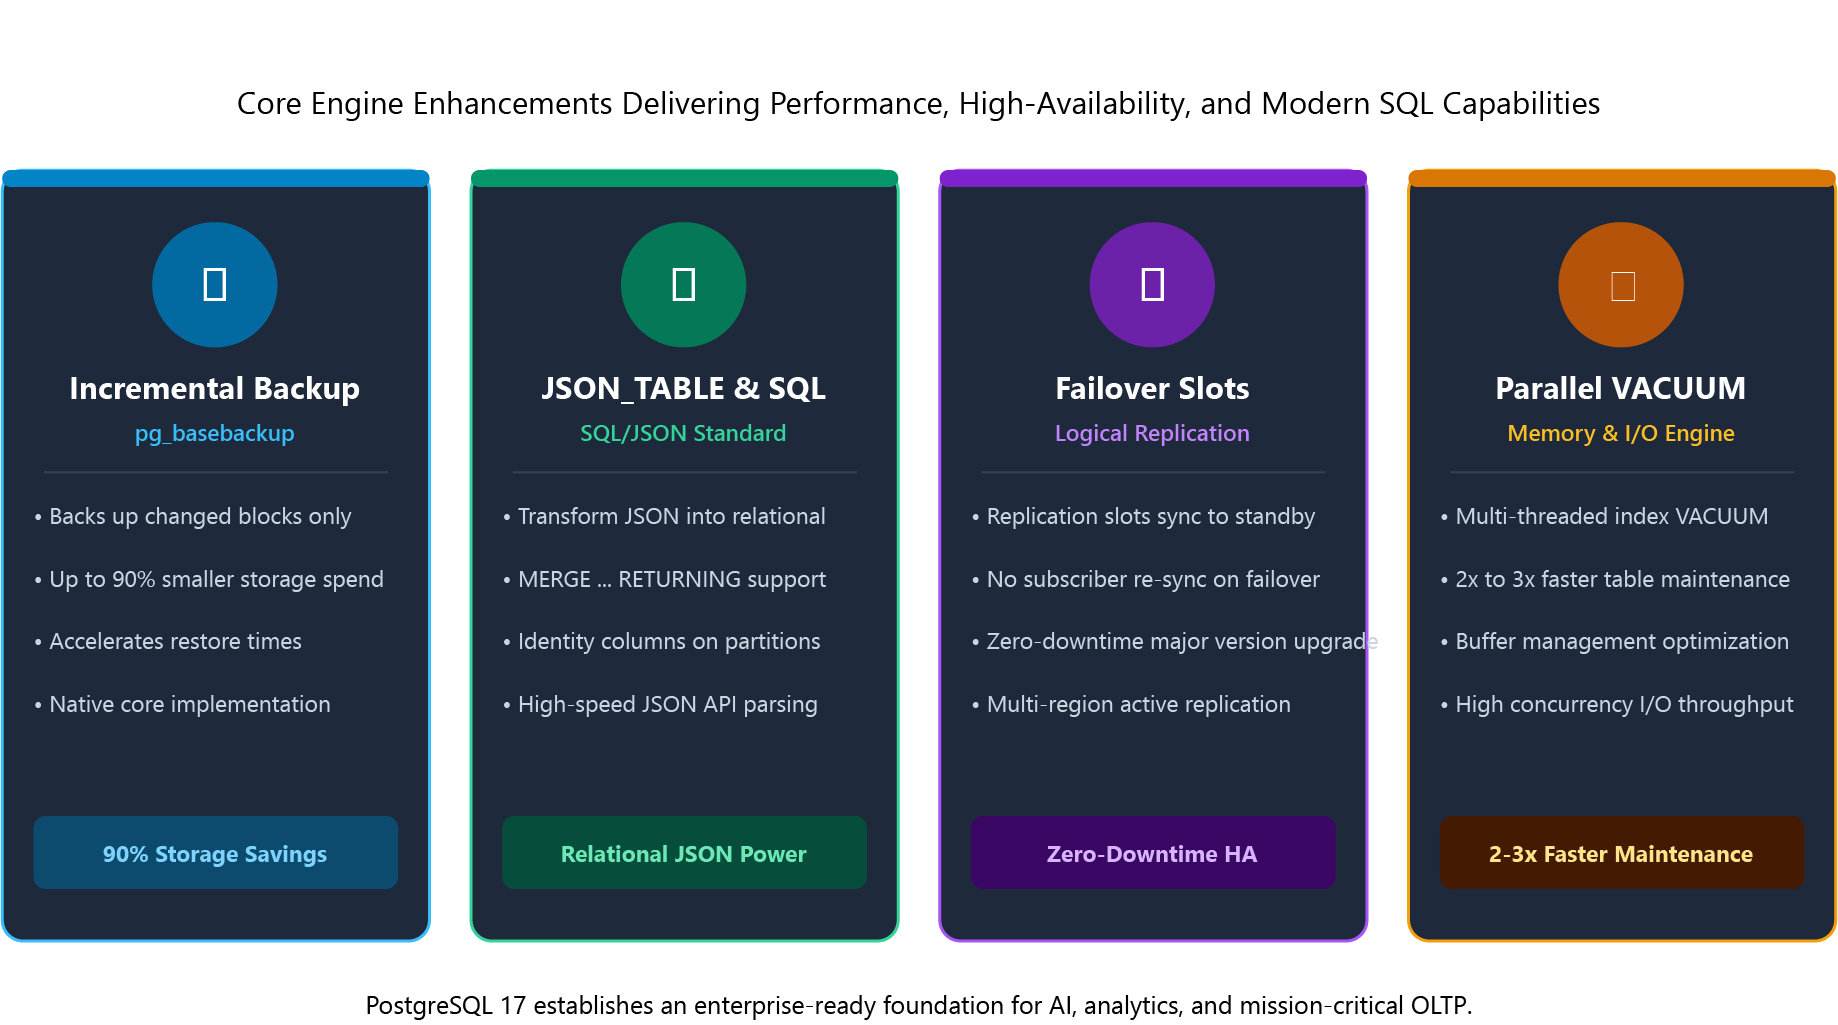
PostgreSQL 17 Key Features
PostgreSQL 17 spans a broad set of improvements, from how the database is backed up to how it handles JSON, replication, and schema changes. The features below are grouped by area, so technical teams can quickly locate what’s relevant to their workload, and business stakeholders can see where each investment area pays off.
| Feature | What’s New | Impact |
| Incremental Backup | pg_basebackup –incremental | 90% smaller backups, faster recovery |
| JSON_TABLE | SQL/JSON standard function | Query JSON as relational tables in SQL |
| Parallel VACUUM | Improved multi-core VACUUM | 2-3x faster maintenance on large tables |
| Logical Replication Failover Slots | Slots survive failover | Zero-downtime logical replication upgrades |
| MERGE Improvements | RETURNING clause, views support | Upsert workflows return affected rows |
| Identity Columns on Partitions | Per-partition identity | Simpler partitioned table design |
| Memory Management | I/O Performance Improvements | Improved buffer management and storage I/O optimization |
Essential PostgreSQL Extension Ecosystem
| Extension | Purpose | Use Case |
| pgvector | Vector similarity search | AI/RAG, semantic search, recommendations |
| PostGIS | Spatial and geographic data | Location services, mapping, geospatial analytics |
| TimescaleDB | Time-series optimization | IoT, metrics, financial tick data |
| Citus | Distributed/sharded PostgreSQL | Multi-tenant SaaS, large-scale analytics |
| pg_cron | In-database job scheduling | Maintenance tasks, data retention policies |
| pgaudit | Audit logging | Compliance (SOX, HIPAA, PCI-DSS) |
| pg_stat_statements | Query performance tracking | Performance tuning and optimization |
| pg_partman | Automated partition management | Time-based data lifecycle management |
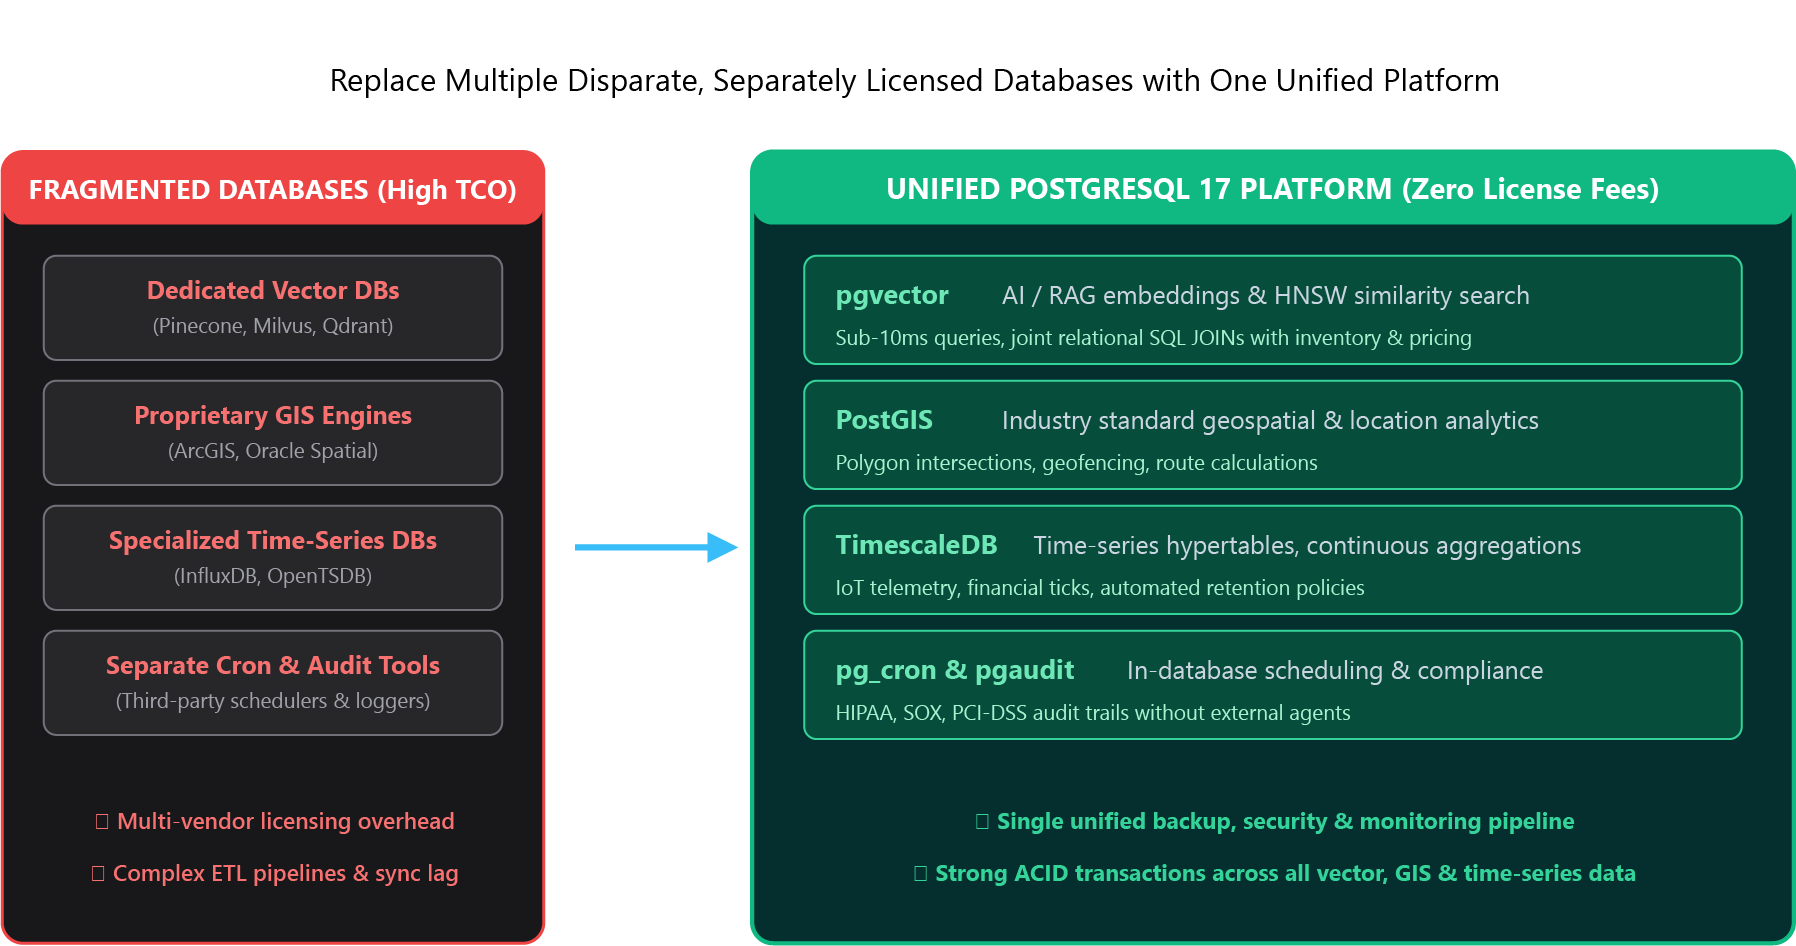
Total Cost of Ownership: PostgreSQL vs. Proprietary Platforms
Database licensing is one of the largest and least visible line items in many enterprise technology budgets, particularly where per-core or per-socket licensing scales faster than the business it supports. PostgreSQL’s open-source licensing model removes that variable entirely, and the extension ecosystem described above compounds the savings: a single PostgreSQL cluster with pgvector, PostGIS, and TimescaleDB can replace what would otherwise be three separately licensed specialty databases, each with its own operational overhead, support contract, and integration surface.
This does not mean PostgreSQL is “free” in a total-cost sense. Organizations still invest in either an internal platform team or a managed service (AlloyDB, Aurora, Cloud SQL, Supabase) to handle patching, high availability, and performance tuning. The financial comparison that matters to a CFO is not licensing cost alone, but the fully loaded cost of ownership such as licensing, infrastructure, staffing, and downtime risk against the equivalent proprietary deployment. For most mid-to-large workloads, that comparison continues to favor PostgreSQL, especially as PG 17’s incremental backup and parallel VACUUM improvements reduce the infrastructure and staff-hours needed for routine operations.
High-Level Use Cases
Use Case 1: AI-Powered Application with pgvector
A SaaS company uses PostgreSQL 17 with pgvector to power its product recommendation engine. Product embeddings are stored alongside relational data, allowing PostgreSQL to perform high-speed vector similarity searches while maintaining ACID transactions. Using an HNSW index, the database returns top-K recommendations in under 10 milliseconds. Standard SQL JOINs then combine the results with user preferences, inventory availability, and pricing information within a single query.
Key Benefits:
- No separate vector database — vectors live with relational data
- Sub-10ms similarity search with HNSW indexing
- ACID transactions ensure recommendations reflect current inventory
- Same operational tooling (backups, monitoring, replication) for vectors
Use Case 2: Global Multi-Region PostgreSQL with Logical Replication
A fintech company uses PostgreSQL 17’s improved logical replication with failover slots to maintain active replicas in 3 regions. Reads are served locally; writes go to the primary. PG 17’s failover slots ensure logical replication subscribers don’t lose their position during primary failover, enabling zero-downtime upgrades.
Key Benefits:
- Sub-50ms read latency globally (local replicas)
- Failover slots eliminate replication re-sync after failover (PG 17 new)
- Incremental backups reduce backup storage by 90%
- JSON_TABLE simplifies ETL from JSON APIs into relational analytics
Best Practices & Recommendations
- Use PgBouncer or Supavisor for connection pooling — PostgreSQL forks a process per connection
- Enable pg_stat_statements and auto_explain for query performance visibility
- Use HNSW index type for pgvector — it’s faster than IVF-Flat for most workloads
- Implement incremental backups (PG 17) to reduce backup storage and recovery time
- Partition large tables by time (pg_partman) and enable parallel VACUUM
- Use logical replication failover slots (PG 17) for zero-downtime upgrades
- Deploy on managed services (AlloyDB, Aurora, Supabase) to offload operational burden
- Monitor bloat with pg_stat_user_tables and schedule regular VACUUM ANALYZE
Conclusion
PostgreSQL 17 delivers meaningful improvements in backup, replication, SQL processing, and database maintenance while continuing to benefit from a mature extension ecosystem. Whether you’re building AI applications, geospatial solutions, SaaS platforms, or large-scale analytics systems, PostgreSQL 17 provides a reliable and scalable foundation for modern enterprise workloads.